Upscale nodes
AI upscaling, repair, enhancement, and restoration.
10 nodes. All sections
- AI Upscale
- Bit Depth Convert
- Downscale 32-bit
- Upscale 32-bit
- Upscale By Size
- Upscale Face Restore
- Upscale Image
- Upscale Router
- Upscale Tiler
- Upscale Video
AI Upscale
RadianceAIUpscale
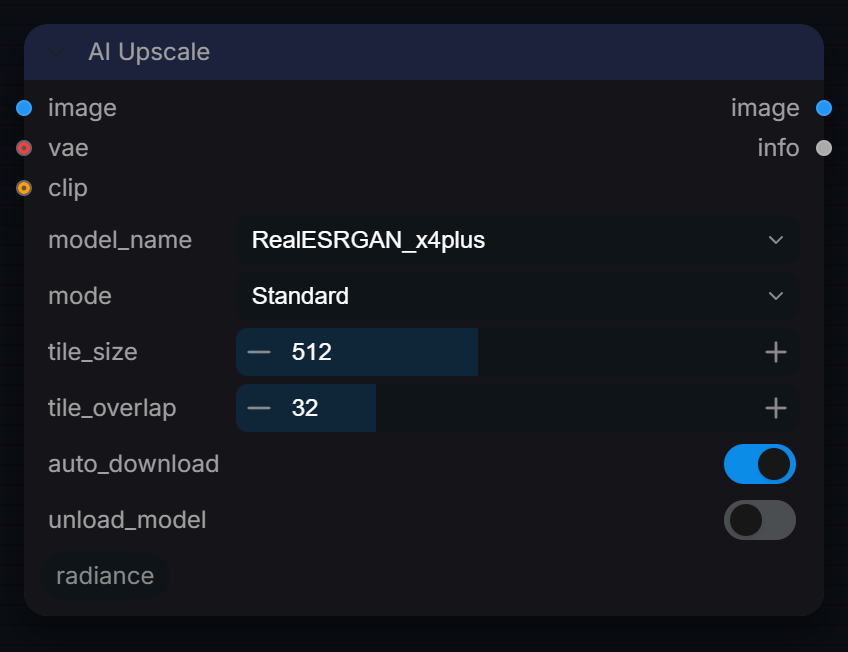
AI-powered upscaling using neural network models. Supports tiled processing for large images.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
image |
IMAGE | Input image to upscale. | ||
model_name |
choice | RealESRGAN_x4plus |
RealESRGAN_x4plus, RealESRGAN_x4plus_anime_6B, RealESRGAN_x2plus, ESRGAN_4x, 4x-UltraSharp, 4x-AnimeSharp, SwinIR_4x, HAT_4x, SUPIR-v0F_fp16, SUPIR-v0Q_fp16 |
AI upscaling model. RealESRGAN_x4plus is recommended for general use. |
mode |
choice | Standard |
Standard, Refine (HDR), Normalize (HDR) |
Processing mode. 'Standard' = direct upscale. 'Refine (HDR)' = log-compression for highlights. 'Normalize (HDR)' = scales to safe range. |
tile_size |
int | 512 | 128 to 1024, step 64 | Tile size for processing. Smaller = less VRAM, slower. |
tile_overlap |
int | 32 | 0 to 128, step 8 | Overlap between tiles to avoid seams. |
auto_download |
boolean | on | Automatically download models if not found. | |
unload_model (optional) |
boolean | off | Unload model from VRAM after processing to free memory. | |
sdxl_model_name (optional) |
string | SUPIR only: filename of your SDXL base checkpoint (e.g. sd_xl_base_1.0_0.9vae.safetensors). Leave empty to auto-detect from the checkpoints folder. Ignored for all non-SUPIR models. | ||
supir_prompt (optional) |
string | multi-line text | SUPIR only: text description for SUPIR upscaling. Leave empty for default conditioning. Ignored for all other models. | |
vae (optional) |
VAE | Reserved for future SUPIR v2 loader support. Currently unused. | ||
clip (optional) |
CLIP | Reserved for future SUPIR v2 loader support. Currently unused. |
Outputs
| Output | Type | What it is |
|---|---|---|
image |
IMAGE | Upscaled image. |
info |
STRING | Information about the upscaling process. |
Bit Depth Convert
RadianceBitDepthConvert
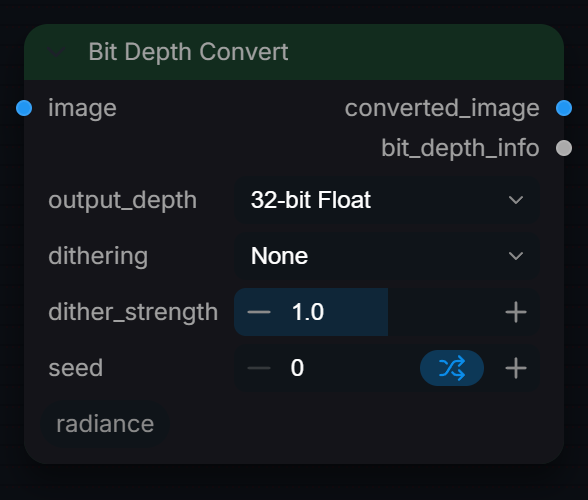
Convert between bit depths with professional dithering to reduce banding.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
image |
IMAGE | Input image in float32 format. | ||
output_depth |
choice | 32-bit Float, 16-bit Float, 16-bit Int, 10-bit, 8-bit |
Target bit depth. | |
dithering (optional) |
choice | None |
None, Floyd-Steinberg, Ordered, Blue Noise, Random |
Dithering algorithm. Floyd-Steinberg = error diffusion, Ordered = Bayer, Blue Noise = high-frequency, Random = simple noise. |
dither_strength (optional) |
float | 1 | 0 to 2, step 0.1 | Dithering intensity. 1.0 = standard. |
seed (optional) |
int | 0 | 0 to 18446744073709551615 | Random seed for reproducible Blue Noise and Random dithering. |
Outputs
| Output | Type | What it is |
|---|---|---|
converted_image |
IMAGE | Image quantized to target bit depth. |
bit_depth_info |
STRING | Information about the conversion. |
Downscale 32-bit
RadianceDownscale32bit
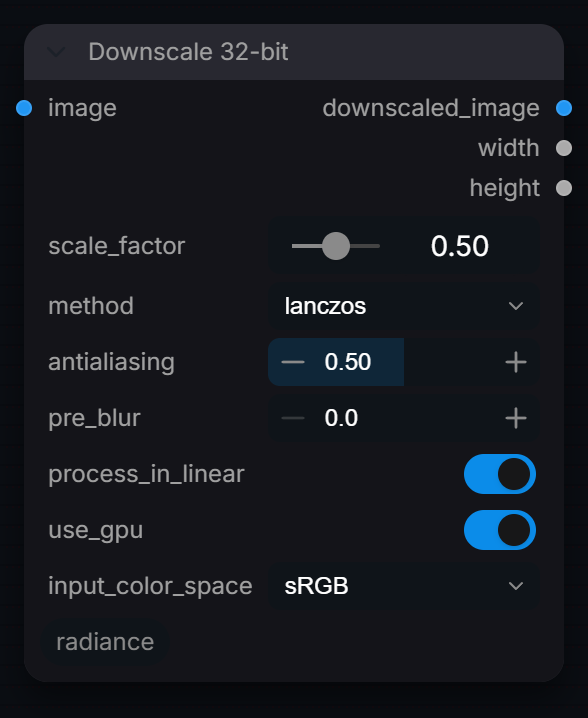
32-bit downscaling with the exact resampling kernel on GPU or CPU and an adjustable anti-aliasing prefilter.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
image |
IMAGE | Image or batch to downscale, display-encoded sRGB or linear float (see input_color_space). Values above 1.0 are kept. | ||
scale_factor |
float | 0.5 | 0.01 to 1, step 0.05 | Output size as a fraction of the input (rounded down, minimum 1 px). |
method |
choice | lanczos, lanczos4, bicubic, mitchell, catrom, gaussian, bilinear |
Resampling kernel, run exactly as named on CUDA and CPU alike: lanczos, lanczos4, bicubic (Catmull-Rom), mitchell, catrom, gaussian, bilinear. | |
antialiasing (optional) |
float | 0.5 | 0 to 1, step 0.05 | Width of the downscaling prefilter. 0.5 = the kernel's textbook width (stretched by the scale factor), 0 = no prefilter (sharpest, aliases and moires), 1 = twice as wide (softest). pre_blur adds a Gaussian on top. |
pre_blur (optional) |
float | 0 | 0 to 2, step 0.1 | Gaussian sigma in input pixels applied before downscaling to suppress aliasing and moire. 0 = off. |
process_in_linear (optional) |
boolean | on | Decode sRGB to linear before resampling and re-encode after, for gamma-correct filtering. Only acts when input_color_space is sRGB; linear/HDR input is never converted. | |
use_gpu (optional) |
boolean | on | Run on CUDA when available (MPS is not used). Falls back to the CPU path, which uses the exact resampling kernels. | |
input_color_space (optional) |
choice | sRGB |
sRGB, Linear, Auto |
Colour space of the input image. Linear skips the sRGB-linear conversion for HDR or already-linear input. Auto: Linear when any value is outside 0-1, else sRGB. |
Outputs
| Output | Type |
|---|---|
downscaled_image |
IMAGE |
width |
INT |
height |
INT |
Upscale 32-bit
RadianceProUpscale
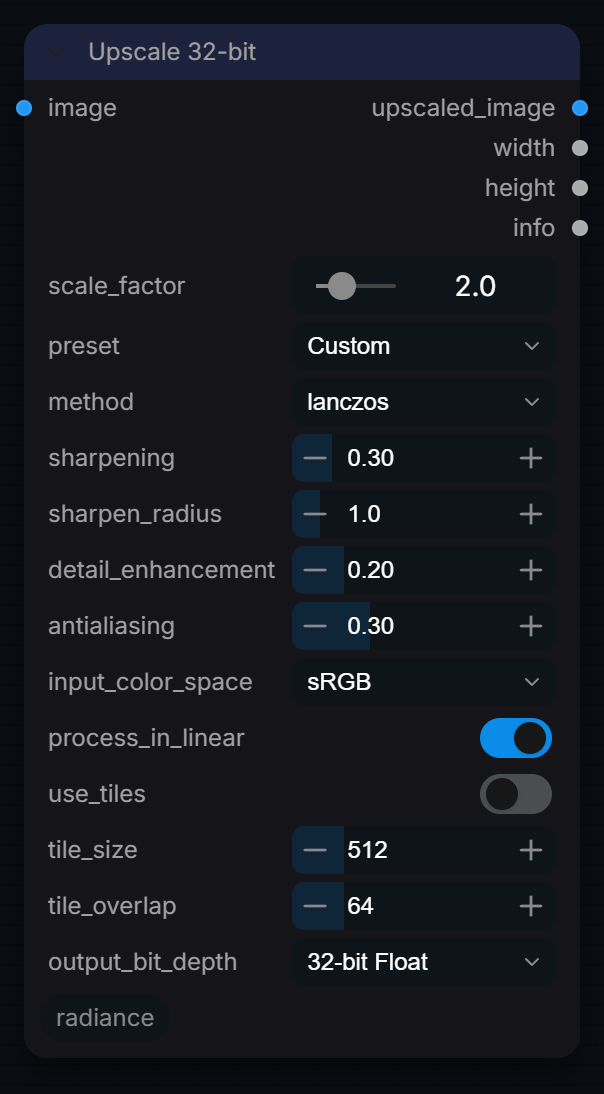
Professional 32-bit upscaler optimized for Flux with HDR support.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
image |
IMAGE | Image or batch to resize, display-encoded sRGB or linear float (see input_color_space). Alpha is resized separately. | ||
scale_factor |
float | 2 | 0.1 to 8, step 0.1 | Output size as a multiple of the input (rounded down to whole pixels). Below 1.0 downscales. |
preset |
choice | Custom, Flux Default, Flux Sharp, Flux Smooth, Flux HDR, Flux Print, Flux Cinematic, Flux Maximum |
Custom uses the widgets below. Any other preset overrides method, sharpening, detail_enhancement and antialiasing, and the HDR/Cinematic presets force process_in_linear on. | |
method (optional) |
choice | lanczos, lanczos4, bicubic, mitchell, catrom, hermite, gaussian, bilinear, nearest |
Resampling kernel, run exactly on every path (GPU, CPU and tiled): lanczos (3 lobes), lanczos4, bicubic and catrom (Catmull-Rom), mitchell (B=C=1/3), hermite, gaussian, bilinear, nearest. | |
sharpening (optional) |
float | 0.3 | 0 to 2, step 0.05 | Unsharp-mask amount applied after resizing. 0 = off, 1 = add the full detail difference once. |
sharpen_radius (optional) |
float | 1 | 0.5 to 5, step 0.1 | Gaussian sigma in output pixels for the unsharp mask. Larger sharpens coarser detail. |
detail_enhancement (optional) |
float | 0.2 | 0 to 1, step 0.05 | Multi-scale luma detail boost (blur sigmas 1, 2 and 4 px) added equally to RGB after resizing. 0 = off. |
antialiasing (optional) |
float | 0.3 | 0 to 1, step 0.05 | Edge-aware softening applied last: blends in a 1 px Gaussian blur in proportion to edge strength. 0 = off; counteracts sharpening on edges. |
input_color_space (optional) |
choice | sRGB, Linear, Auto |
Encoding of the input. sRGB allows the linear-light conversion; Linear leaves values untouched. Auto: Linear when any value is outside 0-1 (HDR), else sRGB; the info output says which. | |
process_in_linear (optional) |
boolean | on | Decode sRGB to linear before resampling and re-encode after, for gamma-correct filtering. Only acts when input_color_space is sRGB; linear/HDR input is never converted. | |
use_tiles (optional) |
boolean | off | Process image in overlapping tiles to handle large images that exceed VRAM. | |
tile_size (optional) |
int | 512 | 128 to 2048, step 64 | Input tile size in pixels for the tiled CPU path. Used only when tiling is on (or forced above 64 MP) and the image is larger than this. |
tile_overlap (optional) |
int | 64 | 16 to 256, step 16 | Overlap in input pixels between tiles, blended to hide seams. Tiled path only. |
output_bit_depth (optional) |
choice | 32-bit Float, 16-bit Float, 8-bit |
Precision of the result (always returned as float). 32-bit keeps values above 1.0; 16-bit rounds to half precision; 8-bit clamps to 0-1 and quantises to 256 levels. |
Outputs
| Output | Type |
|---|---|
upscaled_image |
IMAGE |
width |
INT |
height |
INT |
info |
STRING |
Upscale By Size
RadianceUpscaleBySize
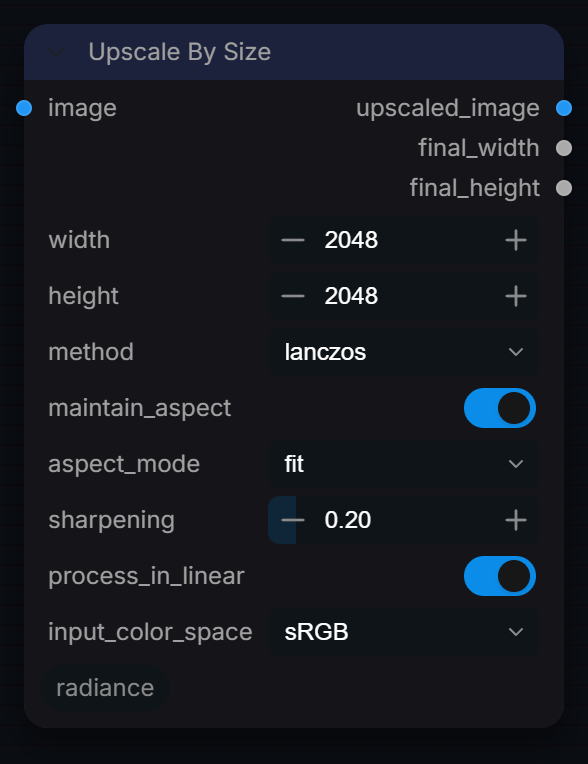
Upscale to exact dimensions with aspect ratio control.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
image |
IMAGE | Image or batch to resize, display-encoded sRGB or linear float (see input_color_space). Alpha is resized separately. | ||
width |
int | 2048 | 64 to 16384, step 8 | Target output width in pixels. |
height |
int | 2048 | 64 to 16384, step 8 | Target output height in pixels. |
method |
choice | lanczos, lanczos4, bicubic, mitchell, catrom, hermite, gaussian, bilinear, nearest |
Resampling kernel, run exactly as named: lanczos (3 lobes), lanczos4, bicubic and catrom (Catmull-Rom), mitchell (B=C=1/3), hermite, gaussian, bilinear, nearest. | |
maintain_aspect (optional) |
boolean | on | Keep the source aspect ratio using aspect_mode to fit the width x height box. Off resizes to exactly width x height. | |
aspect_mode (optional) |
choice | fit, fill, stretch |
With maintain_aspect on. fit: largest size inside the box. fill: smallest size covering the box (not cropped, so one side exceeds it). stretch: exactly width x height. | |
sharpening (optional) |
float | 0.2 | 0 to 2, step 0.05 | Unsharp-mask amount (1 px sigma) applied after resizing. 0 = off. |
process_in_linear (optional) |
boolean | on | Decode sRGB to linear before resampling and re-encode after, for gamma-correct filtering. Only acts when input_color_space is sRGB; linear/HDR input is never converted. | |
input_color_space (optional) |
choice | sRGB |
sRGB, Linear, Auto |
Colour space of the input. Linear skips the sRGB-to-linear conversion for HDR/linear input. Auto: Linear when any value is outside 0-1, else sRGB. |
Outputs
| Output | Type |
|---|---|
upscaled_image |
IMAGE |
final_width |
INT |
final_height |
INT |
Upscale Face Restore
RadianceUpscaleFaceRestore
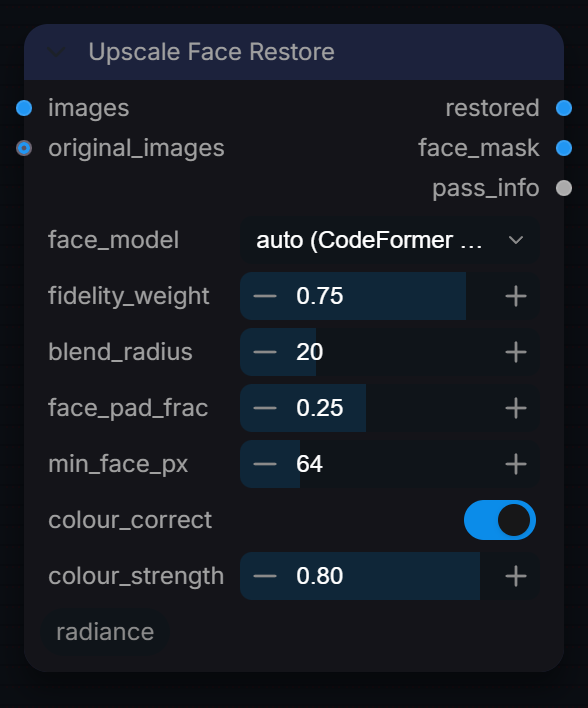
Restore and enhance facial detail using a face restoration model.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
images |
IMAGE | Upscaled image batch (B,H,W,C) float32. | ||
face_model |
choice | auto (CodeFormer → GFPGAN → skip) |
auto (CodeFormer → GFPGAN → skip), codeformer, gfpgan_v1.4, skip (detection only) |
Face restoration model. Auto tries CodeFormer first, falls back to GFPGAN, skips if neither is available. |
fidelity_weight |
float | 0.75 | 0 to 1, step 0.05 | CodeFormer fidelity: 0 = maximum enhancement (creative), 1 = faithful to input (precise). 0.5–0.8 is recommended for most upscaled content. |
blend_radius |
int | 20 | 0 to 80, step 4 | Gaussian feather radius in pixels at face crop edge. Higher = softer transition. 0 = hard paste. |
face_pad_frac |
float | 0.25 | 0 to 0.6, step 0.05 | Extra padding around each detected face bbox (fraction of face width/height). 0.25 = 25%. |
min_face_px |
int | 64 | 16 to 256, step 16 | Smallest face (in pixels) to process. Smaller faces are skipped. |
colour_correct |
boolean | on | Apply histogram-match colour correction after restoration to cancel diffusion colour drift. | |
colour_strength |
float | 0.8 | 0 to 1, step 0.05 | Strength of histogram-match correction. 1.0 = full match to input colours. |
original_images (optional) |
IMAGE | Original (pre-upscale) images for colour reference. Used by histogram-match correction. Leave disconnected to use the restored images as self-reference. |
Outputs
| Output | Type |
|---|---|
restored |
IMAGE |
face_mask |
IMAGE |
pass_info |
STRING |
Upscale Image
RadianceUpscaleImage
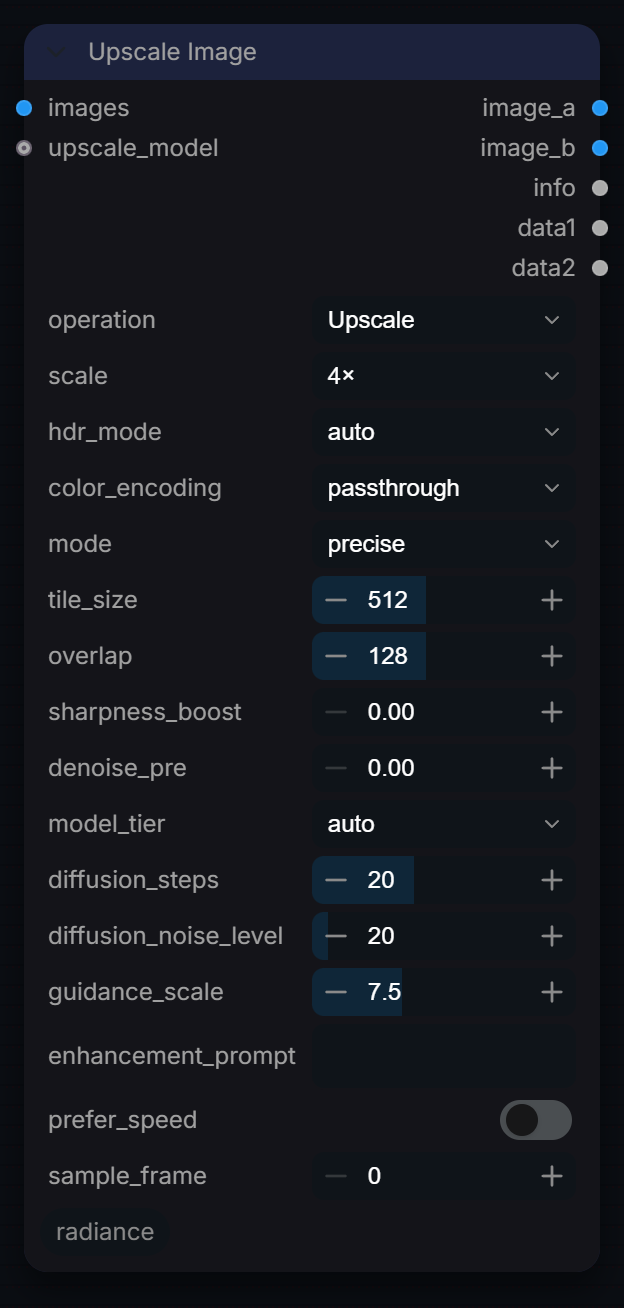
Upscale a still image using a selected super-resolution model.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
operation |
choice | Upscale |
Upscale, Route |
Upscale: run super-resolution. Route: pass images through and output the recommended tier, content class and stats (no upscale). |
images |
IMAGE | Input image batch. | ||
scale (optional) |
choice | 4× |
2×, 4×, 8× (tile cascade) |
Output scale. 8× runs the 4× model twice, the second pass area-downsampled by half. |
hdr_mode (optional) |
choice | auto |
auto, preserve, clamp |
Scene-linear / HDR handling. auto: preserve range when input exceeds 1.0, else clamp. preserve: Reinhard tonemap before SR and re-expand after (keeps highlights >1.0). clamp: legacy [0,1] (LDR). |
color_encoding (optional) |
choice | passthrough |
passthrough, linear<->sRGB, linear<->LogC3 |
Encode scene-linear -> display (sRGB/LogC3) before SR and decode after, so the LDR-trained network sees the domain it expects. passthrough: feed pixels unchanged. |
mode (optional) |
choice | precise |
precise, creative, balanced |
precise: Real-ESRGAN fidelity-first. creative: diffusion detail hallucination (requires VRAM). balanced: GAN upscale + light sharpening. |
tile_size (optional) |
int | 512 | 128 to 1024, step 64 | Tile size in input pixels. Reduce if OOM. |
overlap (optional) |
int | 128 | 32 to 256, step 32 | Overlap between tiles in input pixels, blended to hide seams. |
sharpness_boost (optional) |
float | 0 | 0 to 1, step 0.05 | Unsharp mask strength applied after upscale. |
denoise_pre (optional) |
float | 0 | 0 to 1, step 0.05 | Gaussian pre-denoise strength. |
upscale_model (optional) |
UPSCALE_MODEL | Optional ComfyUI UPSCALE_MODEL; its native scale should match scale. When connected it replaces the built-in tiers (model_tier and creative mode are ignored). | ||
model_tier (optional) |
choice | auto |
auto, tier1_fast (Real-ESRGAN — GAN, ms/frame), tier2_quality (HAT-L — transformer SOTA PSNR), tier2_quality (SwinIR-L — transformer quality), tier3_creative (SD x4 — diffusion hallucination), tier3_creative (SeedVR2 — one-step video diffusion) |
Model tier. 'auto' selects based on content analysis. |
diffusion_steps (optional) |
int | 20 | 1 to 50, step 1 | Inference steps for Tier 3 diffusion (creative mode or a tier3 model_tier). More steps are slower; SeedVR2 is one-step. |
diffusion_noise_level (optional) |
int | 20 | 0 to 350, step 10 | SD x4 upscaler only: noise added to the low-res input. Higher lets the model invent more detail and drift further from the source. |
guidance_scale (optional) |
float | 7.5 | 1 to 20, step 0.5 | SD x4 upscaler only: classifier-free guidance toward enhancement_prompt. Higher follows the prompt more strongly. |
enhancement_prompt (optional) |
string | Text prompt for creative mode diffusion steering. | ||
prefer_speed (optional) |
boolean | off | Always recommend Tier 1 fast regardless of content. | |
sample_frame (optional) |
int | 0 | 0 to 9999 | Index of frame to analyse (for Route operation). |
Outputs
| Output | Type |
|---|---|
image_a |
IMAGE |
image_b |
IMAGE |
info |
STRING |
data1 |
STRING |
data2 |
STRING |
Upscale Router
RadianceUpscaleRouter
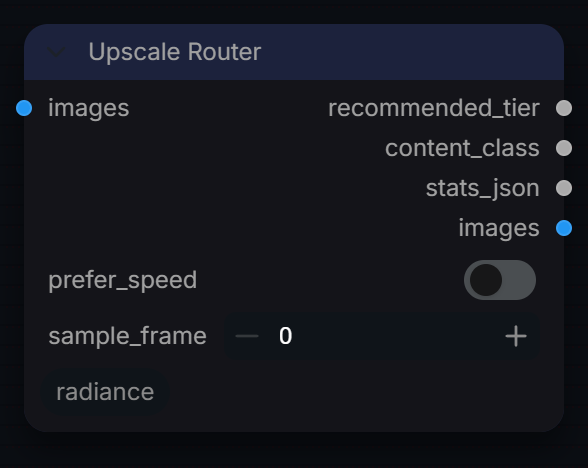
Measure noise, sharpness and saturation on one frame and recommend a model_tier for Upscale Image or Video. Heuristic statistics only; images pass through unchanged.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
images |
IMAGE | Image or frame batch to analyse; returned unchanged on the images output. | ||
prefer_speed |
boolean | off | Always recommend Tier 1 fast regardless of content. | |
sample_frame |
int | 0 | 0 to 9999 | Index of frame to analyse (for video batches). |
Outputs
| Output | Type |
|---|---|
recommended_tier |
STRING |
content_class |
STRING |
stats_json |
STRING |
images |
IMAGE |
Upscale Tiler
RadianceUpscaleTiler
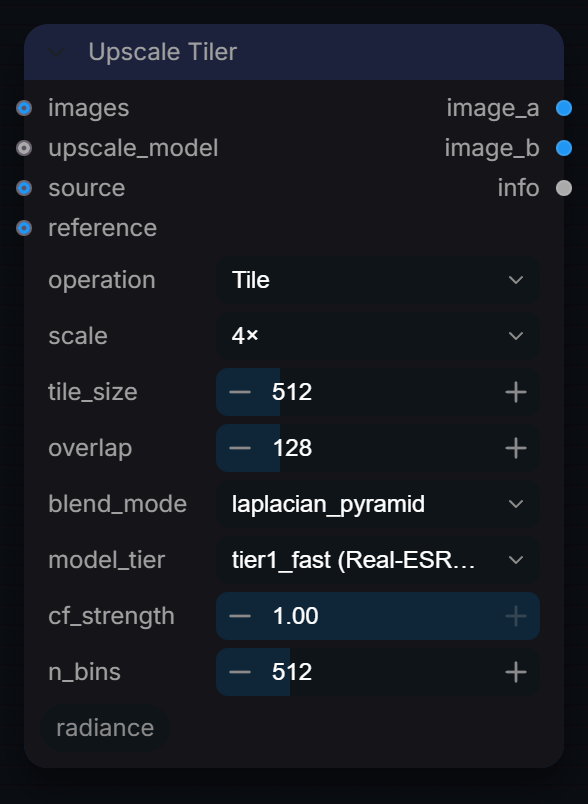
Tile large images into overlapping patches for memory-safe upscaling.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
operation |
choice | Tile |
Tile, ColourFix |
Tile: tiled upscale of images (output clamped to 0-1). ColourFix: histogram-match source to reference to remove upscaler colour drift. |
images (optional) |
IMAGE | Input image batch (B,H,W,C) float32. | ||
scale (optional) |
choice | 4× |
2×, 4×, 8× (tile cascade) |
Upscale factor. 8× uses two cascaded 4× passes. |
tile_size (optional) |
int | 512 | 128 to 2048, step 64 | Tile side in input pixels. Smaller = less VRAM. |
overlap (optional) |
int | 128 | 32 to 512, step 32 | Tile overlap in input pixels. ≥20% of tile_size recommended. |
blend_mode (optional) |
choice | laplacian_pyramid |
laplacian_pyramid, gaussian_feather, linear |
laplacian_pyramid: best quality. gaussian_feather: fast. linear: simple. |
upscale_model (optional) |
UPSCALE_MODEL | Any ComfyUI UPSCALE_MODEL; its native scale should match scale. Leave empty to use the built-in model chosen by model_tier. | ||
model_tier (optional) |
choice | tier1_fast (Real-ESRGAN — GAN, ms/frame) |
auto, tier1_fast (Real-ESRGAN — GAN, ms/frame), tier2_quality (HAT-L — transformer SOTA PSNR), tier2_quality (SwinIR-L — transformer quality), tier3_creative (SD x4 — diffusion hallucination), tier3_creative (SeedVR2 — one-step video diffusion) |
Built-in model tier when no upscale_model is connected. |
source (optional) |
IMAGE | Upscaled image with colour drift (ColourFix mode). | ||
reference (optional) |
IMAGE | Original pre-upscale image — colour reference (ColourFix mode). | ||
cf_strength (optional) |
float | 1 | 0 to 1, step 0.05 | ColourFix strength: 0 = off, 1 = full CDF match. |
n_bins (optional) |
int | 512 | 64 to 2048, step 64 | Histogram resolution (ColourFix mode). |
Outputs
| Output | Type |
|---|---|
image_a |
IMAGE |
image_b |
IMAGE |
info |
STRING |
Upscale Video
RadianceUpscaleVideo
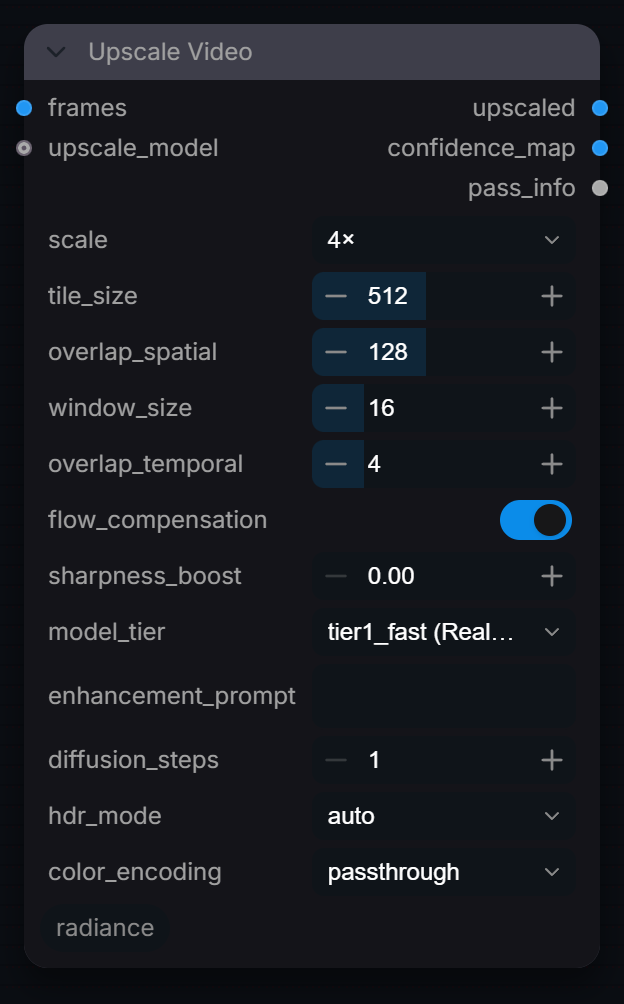
Upscale a video sequence using a selected super-resolution model.
Inputs
| Input | Type | Default | Range or choices | What it does |
|---|---|---|---|---|
frames |
IMAGE | Video frame batch (B,H,W,C) float32. B = frame count. | ||
scale |
choice | 4× |
2×, 4×, 8× (tile cascade) |
Output scale. 8× runs the 4× model twice, the second pass area-downsampled by half. |
tile_size |
int | 512 | 128 to 1024, step 64 | Spatial tile size in input pixels. Reduce if OOM. |
overlap_spatial |
int | 128 | 32 to 256, step 32 | Spatial tile overlap in input pixels. |
window_size |
int | 16 | 4 to 64, step 4 | Frames per processing batch (VRAM). Tier 1/2 models are single-image: each frame is still upscaled on its own. |
overlap_temporal |
int | 4 | 1 to 16, step 1 | Frames shared between adjacent windows. Minimum 1 for seam-free stitching. |
flow_compensation |
boolean | on | At window seams each overlap frame is upscaled twice; Lucas-Kanade flow aligns the two results before they are blended. It does not compensate camera motion between frames. | |
sharpness_boost |
float | 0 | 0 to 1, step 0.05 | Unsharp-mask strength (sigma 1.5 px) applied after upscaling. 0 = off. |
upscale_model (optional) |
UPSCALE_MODEL | Optional ComfyUI UPSCALE_MODEL; its native scale should match scale. When connected it replaces model_tier. | ||
model_tier (optional) |
choice | tier1_fast (Real-ESRGAN — GAN, ms/frame) |
auto, tier1_fast (Real-ESRGAN — GAN, ms/frame), tier2_quality (HAT-L — transformer SOTA PSNR), tier2_quality (SwinIR-L — transformer quality), tier3_creative (SD x4 — diffusion hallucination), tier3_creative (SeedVR2 — one-step video diffusion) |
Select 'SeedVR2' for best temporal consistency on video. Requires seedvr2 or diffusers package. |
enhancement_prompt (optional) |
string | Text prompt for Tier 3 diffusion steering (e.g. 'cinematic film grain, detailed textures'). | ||
diffusion_steps (optional) |
int | 1 | 1 to 50, step 1 | Diffusion inference steps. SeedVR2 uses 1 (one-step); SD x4 upscaler recommended 15-25. |
hdr_mode (optional) |
choice | auto |
auto, preserve, clamp |
Scene-linear / HDR handling. auto: preserve range when input exceeds 1.0, else clamp. preserve: Reinhard tonemap before SR and re-expand after. clamp: legacy [0,1] (LDR). |
color_encoding (optional) |
choice | passthrough |
passthrough, linear<->sRGB, linear<->LogC3 |
Encode scene-linear -> display (sRGB/LogC3) before SR and decode after. passthrough: feed pixels unchanged. |
Outputs
| Output | Type |
|---|---|
upscaled |
IMAGE |
confidence_map |
IMAGE |
pass_info |
STRING |